Most ecommerce sites do not become slow because engineers forget how to write fast code. They become slow because nobody owns the accumulated cost of everything added around it.
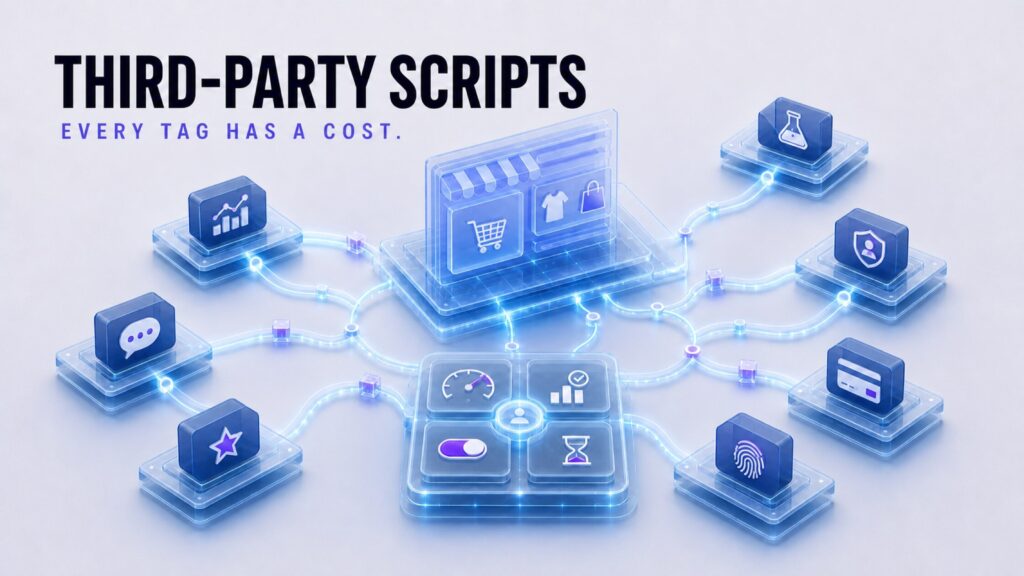
One team needs analytics. Another needs experimentation. Marketing adds attribution. Customer service adds chat. Merchandising adds recommendations and reviews. Payments and fraud teams need their own integrations. Each request can be reasonable in isolation.
The browser does not see the organisation chart. It downloads, parses and executes the combined result.
That is why third-party scripts are not only a frontend optimisation problem. They are a leadership problem: a question of who can introduce cost, who is accountable for value, and who has the authority to remove something when the trade-off no longer makes sense.
Every script arrives with a reasonable request
It is easy to turn this discussion into “engineering versus marketing”. That framing is both unhelpful and inaccurate. Third-party tools often provide real capabilities faster than a team could build them: payments, fraud prevention, consent management, analytics, site search, personalisation, product reviews and customer service.
The problem is not that the tools exist. It is that the decision to add one is often local while its effects are shared.
A tag commissioned for one campaign can execute on every product page. A chat widget can compete with the code handling add-to-basket interactions. An experimentation platform can alter page rendering before the customer sees anything useful. A tag manager change can reach production without passing through the same review path as application code.
No single request looks decisive. Over time, the storefront becomes the integration layer for a portfolio of vendors, each with its own network, JavaScript, release cycle and view of the customer.
The bill is bigger than page speed
Performance is the most visible cost, but it is only one part of the bill.
Third-party code can add network connections, block rendering, consume main-thread time and delay interaction feedback. Loading a script asynchronously may stop it blocking the HTML parser, but it does not make its execution free. Work that happens after the page looks ready can still interfere with taps, filters, menus and checkout interactions. That matters because Interaction to Next Paint measures responsiveness across the life of a visit, not just during initial load.
There is also a reliability cost. The storefront now depends on systems the team does not operate. A slow vendor, failed request or incompatible update can create errors in a customer journey that the retailer still owns. If a tool is unavailable, the desired failure mode should be known: does the page continue, does a feature disappear cleanly, or does the purchase path break?
Security and privacy widen the boundary again. JavaScript running in the page may be able to read or change far more than the narrow feature that justified it. Tags can access page data, initiate requests and change without the host application being redeployed. Consent requirements, data minimisation and vendor access therefore belong in the integration decision, not in a checklist added at the end.
Finally, there is a maintenance cost. When a production issue appears only for certain customers, regions, consent states or campaign parameters, engineers have to reason about code they did not write and may not be able to inspect. The cost appears in slower diagnosis, fragile workarounds and uncertainty about what can safely be removed.
Engineering cannot solve this alone
Frontend teams have useful controls. They can apply async or defer where appropriate, delay non-critical tools, restrict scripts to the pages that need them, isolate some integrations, improve the data layer and measure execution cost. Content Security Policy, Subresource Integrity and sandboxing can reduce particular risks when the vendor and delivery model support them.
None of those techniques can decide whether the business value justifies the total cost.
Engineering can show that a tool adds main-thread work or creates a failure mode. It cannot decide alone whether the attribution insight, fraud reduction or service improvement is worth it. Equally, a vendor dashboard showing engagement cannot decide whether the experience is still acceptable on a mid-range phone.
The decision needs business context and technical evidence in the same room — the same accountability mindset as practical AI in engineering, where judgment matters more than throughput.
Give every integration an owner, a budget and an expiry date
The simplest governance model starts with a rule: nothing runs indefinitely without an accountable owner.
For every third-party integration, record:
- the named business owner;
- the customer or commercial outcome it is meant to improve;
- the pages and journeys where it is allowed to run;
- the data it reads, stores or sends;
- its loading and consent conditions;
- its expected performance and reliability cost;
- how its value will be measured;
- what should happen if it fails;
- how it can be disabled; and
- the date on which it must be reviewed or removed.
The owner does not need to understand every line of JavaScript. They do need to remain accountable for the reason it is there. “Marketing” is not an owner. Neither is “the agency”, “the platform team” or a ticket that closed eighteen months ago.
An expiry date changes the default. Instead of a script staying forever because nobody wants to challenge it, continued use becomes a decision supported by current evidence.
Measure value and cost together
A performance budget is useful, but it should not become a single number that teams learn to work around. Track the costs that match the integration: transferred bytes, extra origins, main-thread time, long tasks, layout movement, effects on Largest Contentful Paint and Interaction to Next Paint, and errors in important journeys.
Use field data where possible. Lab tests are excellent for controlled comparison, but real-user monitoring shows how the integration behaves across actual devices, networks, pages and consent states. Segment the data carefully; an average can hide the customers receiving the worst experience.
Then place those costs beside evidence of value. That might be incremental conversion, fraud prevented, support contacts resolved or experiments that materially changed a decision. Vendor-reported activity is an input, not proof of incrementality.
Blocking a vendor domain in a controlled test can reveal what it contributes to page weight and execution. A properly designed holdout or phased rollout can help establish whether it contributes to the outcome it claims. The important move is to stop discussing value and performance in separate meetings.
Procurement decisions are architecture decisions
If a service ships code into the product page or checkout, procurement has made an architectural decision whether it calls it one or not.
Technical due diligence should happen before the contract removes most of the leverage. Teams should understand the delivery model, data flows, release controls, browser permissions, regional behaviour, failure modes and exit path. Ask whether the tool can run only where needed, whether it respects consent before loading, whether changes are versioned, and whether the integration can be disabled without waiting for the vendor.
The right answer is not always “do not buy”. It may be to use a server-to-server API instead of broad client-side access, expose a controlled data layer, lazy-load an interface after interaction, or start on a narrow set of pages. The integration shape is part of the product decision.
Governance should make good decisions faster
Governance does not need to mean a monthly committee that turns every tag into a negotiation. A good operating model creates a paved path for low-risk changes and more scrutiny for code that reaches high-value or sensitive journeys.
A practical flow looks like this:
- Make the inventory visible. List what runs, where it runs, who owns it and what data it touches.
- Remove the orphans. Disable tools with no owner, no current purpose or a superseded capability before spending time optimising them.
- Test the real journey. Measure representative product, listing, account and checkout paths on realistic devices, not only the homepage on a developer laptop.
- Choose the narrowest scope. Load the integration only on the pages, consent states and interactions that require it.
- Define the failure mode. The core customer journey should degrade deliberately when the vendor is slow or unavailable.
- Measure after release. Compare performance, errors and the intended business outcome, then keep, change or remove the integration.
- Review the portfolio. Revisit owners, costs and evidence on a regular cadence and after material vendor changes.
The team also needs a kill switch that works. Discovering during an incident that nobody has tag-manager access, or that disabling a vendor breaks another undocumented dependency, is evidence that ownership existed on paper only.
Questions leaders should be able to answer
For any third-party script on a critical journey, ask:
- What customer or business outcome does this improve?
- What evidence shows that the improvement is incremental?
- Why does it need to run on this page and at this moment?
- What code and data can the vendor access?
- What happens when it is slow, blocked or unavailable?
- Who will notice if its behaviour changes?
- Who can disable it safely?
- When will we decide whether to keep it?
If those questions have no clear answers, the integration is not governed. It is merely present.
The leadership work is cumulative
There is no permanent “clean-up complete” state. Ecommerce estates change too quickly: campaigns start, vendors consolidate, teams reorganise and capabilities move into the commerce platform itself. Without a recurring ownership model, today’s justified addition becomes tomorrow’s invisible dependency.
Leaders do not need to approve every script personally. They need to make the system-level trade-off visible, give teams shared guardrails and support removal as a legitimate delivery outcome. Deleting an unnecessary tag can be as valuable as launching a new one, even when it produces a less impressive roadmap slide.
This is part of staying close to the craft: not doing every optimisation yourself, but remaining close enough to understand where technical friction is really coming from and how organisational decisions reach the customer experience. The same foundation thinking shows up in AEO and GEO for ecommerce — new discovery interfaces still depend on a storefront that loads, responds and remains trustworthy.
Third-party scripts are useful. They are also code, dependencies and data relationships executing inside a product the business is accountable for. Treating them that way is not engineering obstruction. It is engineering leadership.